10 Aug 2023
Optimized invoice & receipt models + Regular expressions
Optimized invoice & receipt models
We’re introducing our optimized invoice and receipt models, which are specific pre-trained models that use machine learning instead of large language models (LLMs). Trained on tens of thousands of example documents, these models have already demonstrated their effectiveness in improving data extraction for a number of our clients.
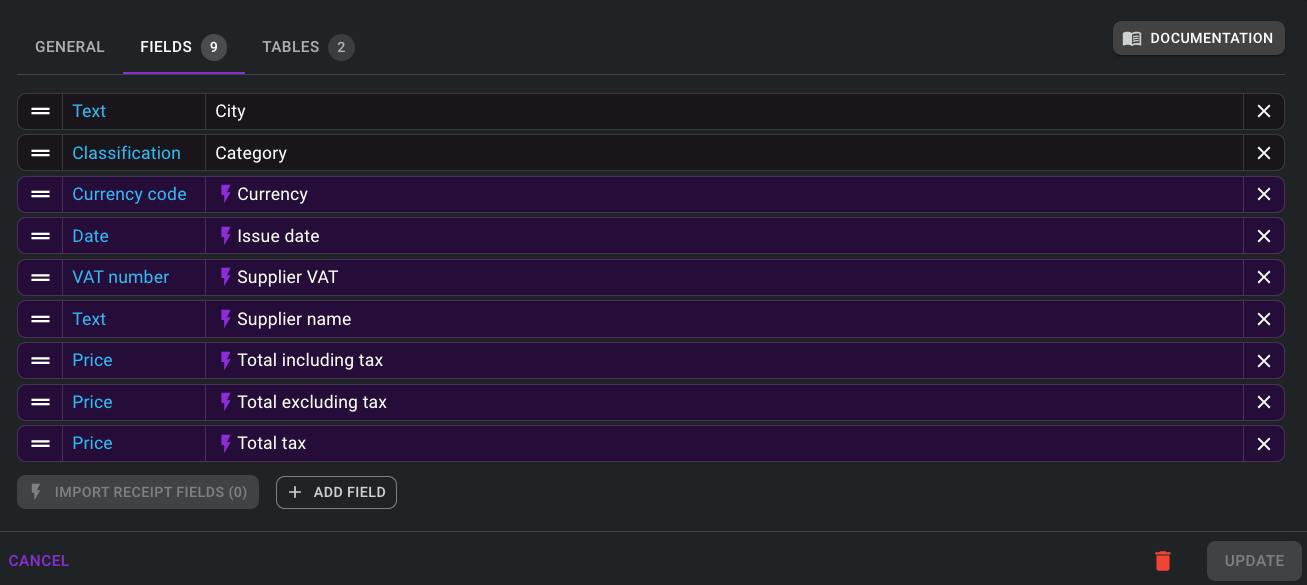
These optimized models can be used independently or in combination with LLMs, providing you with added flexibility. For example, you could configure Skwiz to use the optimized receipt model to extract essential data such as amounts, the issue date, supplier information and tables from your documents. LLM could then be used in addition to find a custom field (say the City) and categorize the content of the receipts in your specific classes, like “Restaurant”, “Hotel” or “Transport” in the field Category. Below you’ll find an example of such a configuration.
Regular expression
To further enhance the flexibility in data extraction, we’ve also added the possibility to define your own regular expressions (regex) and link these to your fields.
Even with the advanced capabilities of our optimized models and LLMs, the precision and efficiency of regex remains critical in the processing of documents. Particularly for pattern recognition in structured text, regex significantly outperforms models in instances where specific patterns can be identified and differentiated from surrounding text.
For example, if the Purchase Order number on your incoming invoices always consists of "PO" followed by 5 digits (e.g. “PO93438”), using regex (in this case `PO\d{5}`) will ensure flawless extraction from each document.